- Redaction must protect sensitive data without disrupting extraction accuracy, document structure, or downstream automation workflows.
- True redaction removes underlying information; visual black boxes can still leave sensitive text recoverable digitally.
- Extracting data before redaction usually preserves context, reduces exceptions, and keeps automated document workflows reliable.
Redaction is now a standard data-protection control in document-heavy workflows such as mortgage, insurance, and accounts payable. Teams often need to share files with investors, reinsurers, vendors, auditors, or internal reviewers without exposing sensitive information. The challenge that breaks the downstream workflow here is that redaction and extraction can interfere with each other.
A document may look safe to a person while still exposing hidden text to an extraction engine. In other cases, removing a value can disrupt the layout or context that an AI model uses to identify nearby fields. For document operations teams, compliance officers, and implementation leads, the goal is therefore not simply to hide data. It is to apply redaction in IDP in a way that protects sensitive content without reducing extraction accuracy, breaking field relationships, or creating more manual review.
What Is Redaction in Document Automation?
Redaction in document automation permanently removes or conceals sensitive information before a file is shared, displayed, or exported. Targets may include PII, PHI, account numbers, payment data, or any other confidential terms. True redaction removes the underlying information so it cannot be recovered from the file.
Reversible masking is different because the original value still exists but is hidden from selected users. Highlighting and annotation only mark content. This distinction matters in redaction in IDP because a black rectangle can look secure while leaving the original characters available to OCR, PDF text extraction, search, or copy-and-paste tools.
Why Redaction Has Become Non-Negotiable
Organizations now process sensitive data through automated document workflows, so downstream sharing needs stronger controls than simple screen-level hiding. HHS defines specific methods for de-identifying protected health information under HIPAA, while PCI DSS separates display masking from methods that make stored payment card data unreadable. Investor agreements, reinsurer contracts, discovery obligations, and internal privacy policies can add further restrictions.
Where Redaction Shows Up in Document Workflows
How Redaction Can Interfere With AI Extraction
Redaction changes what an extraction model can see, where information appears, and which context remains available. Those changes can affect OCR, layout analysis, field matching, and document linking throughout processing.
How OCR and Layout Models Read a Page
Extraction systems may use OCR coordinates, word order, table boundaries, labels, page geometry, and embedded PDF text. Layout-aware models also use relative field position and nearby visual cues. Removing text or altering coordinates can therefore affect fields that were never meant to be hidden.
When a Black Box Isn't Actually Redaction
Some PDF tools place a visual box over sensitive text without deleting the content below it. A person sees redaction, but search, copy-and-paste, OCR, or an extraction engine may still recover the underlying text. The document looks protected while the sensitive data remains accessible. Improper PDF sanitization has produced documented cases where supposedly redacted text remained recoverable.
When Redaction Breaks Field Positioning
Removing content can change spacing, table structure, or nearby anchors. If a model depends on labels, coordinates, or relative position, deleting an entire region can weaken field relationships. That can cause extraction errors in nearby values or alter how a table is interpreted.
When Redaction Removes Context a Model Needs
Sensitive values may also act as workflow keys. A policy, account, or loan number can link a document to the right record. If it disappears before matching occurs, extraction may succeed while the wider workflow fails, creating unmatched documents or reconciliation work.
The Cost of Getting Redaction-Aware Extraction Wrong
Poor redaction design creates problems on both sides of the workflow. If a file is redacted too early, extraction accuracy can fall, and straight-through processing can drop. Teams then re-key values, rebuild document links, or route more pages to manual review. That increases processing time and removes much of the value of automation.
The opposite failure is more serious from a privacy perspective. A document can appear redacted while its underlying text remains available to software or recipients. That creates unnecessary exposure during sharing, audit, litigation, or third-party processing. Broken identifiers can also cause reconciliation errors, such as attaching a document to the wrong record or failing to match an invoice to the correct vendor. Redaction-aware extraction needs to protect the data while preserving the signals that downstream automation still requires.
How to Approach Redaction Without Breaking Extraction
The safest design treats extraction and redaction as coordinated stages. Teams should define sequencing, file treatment, structural preservation, and access rules before redacted documents move downstream.
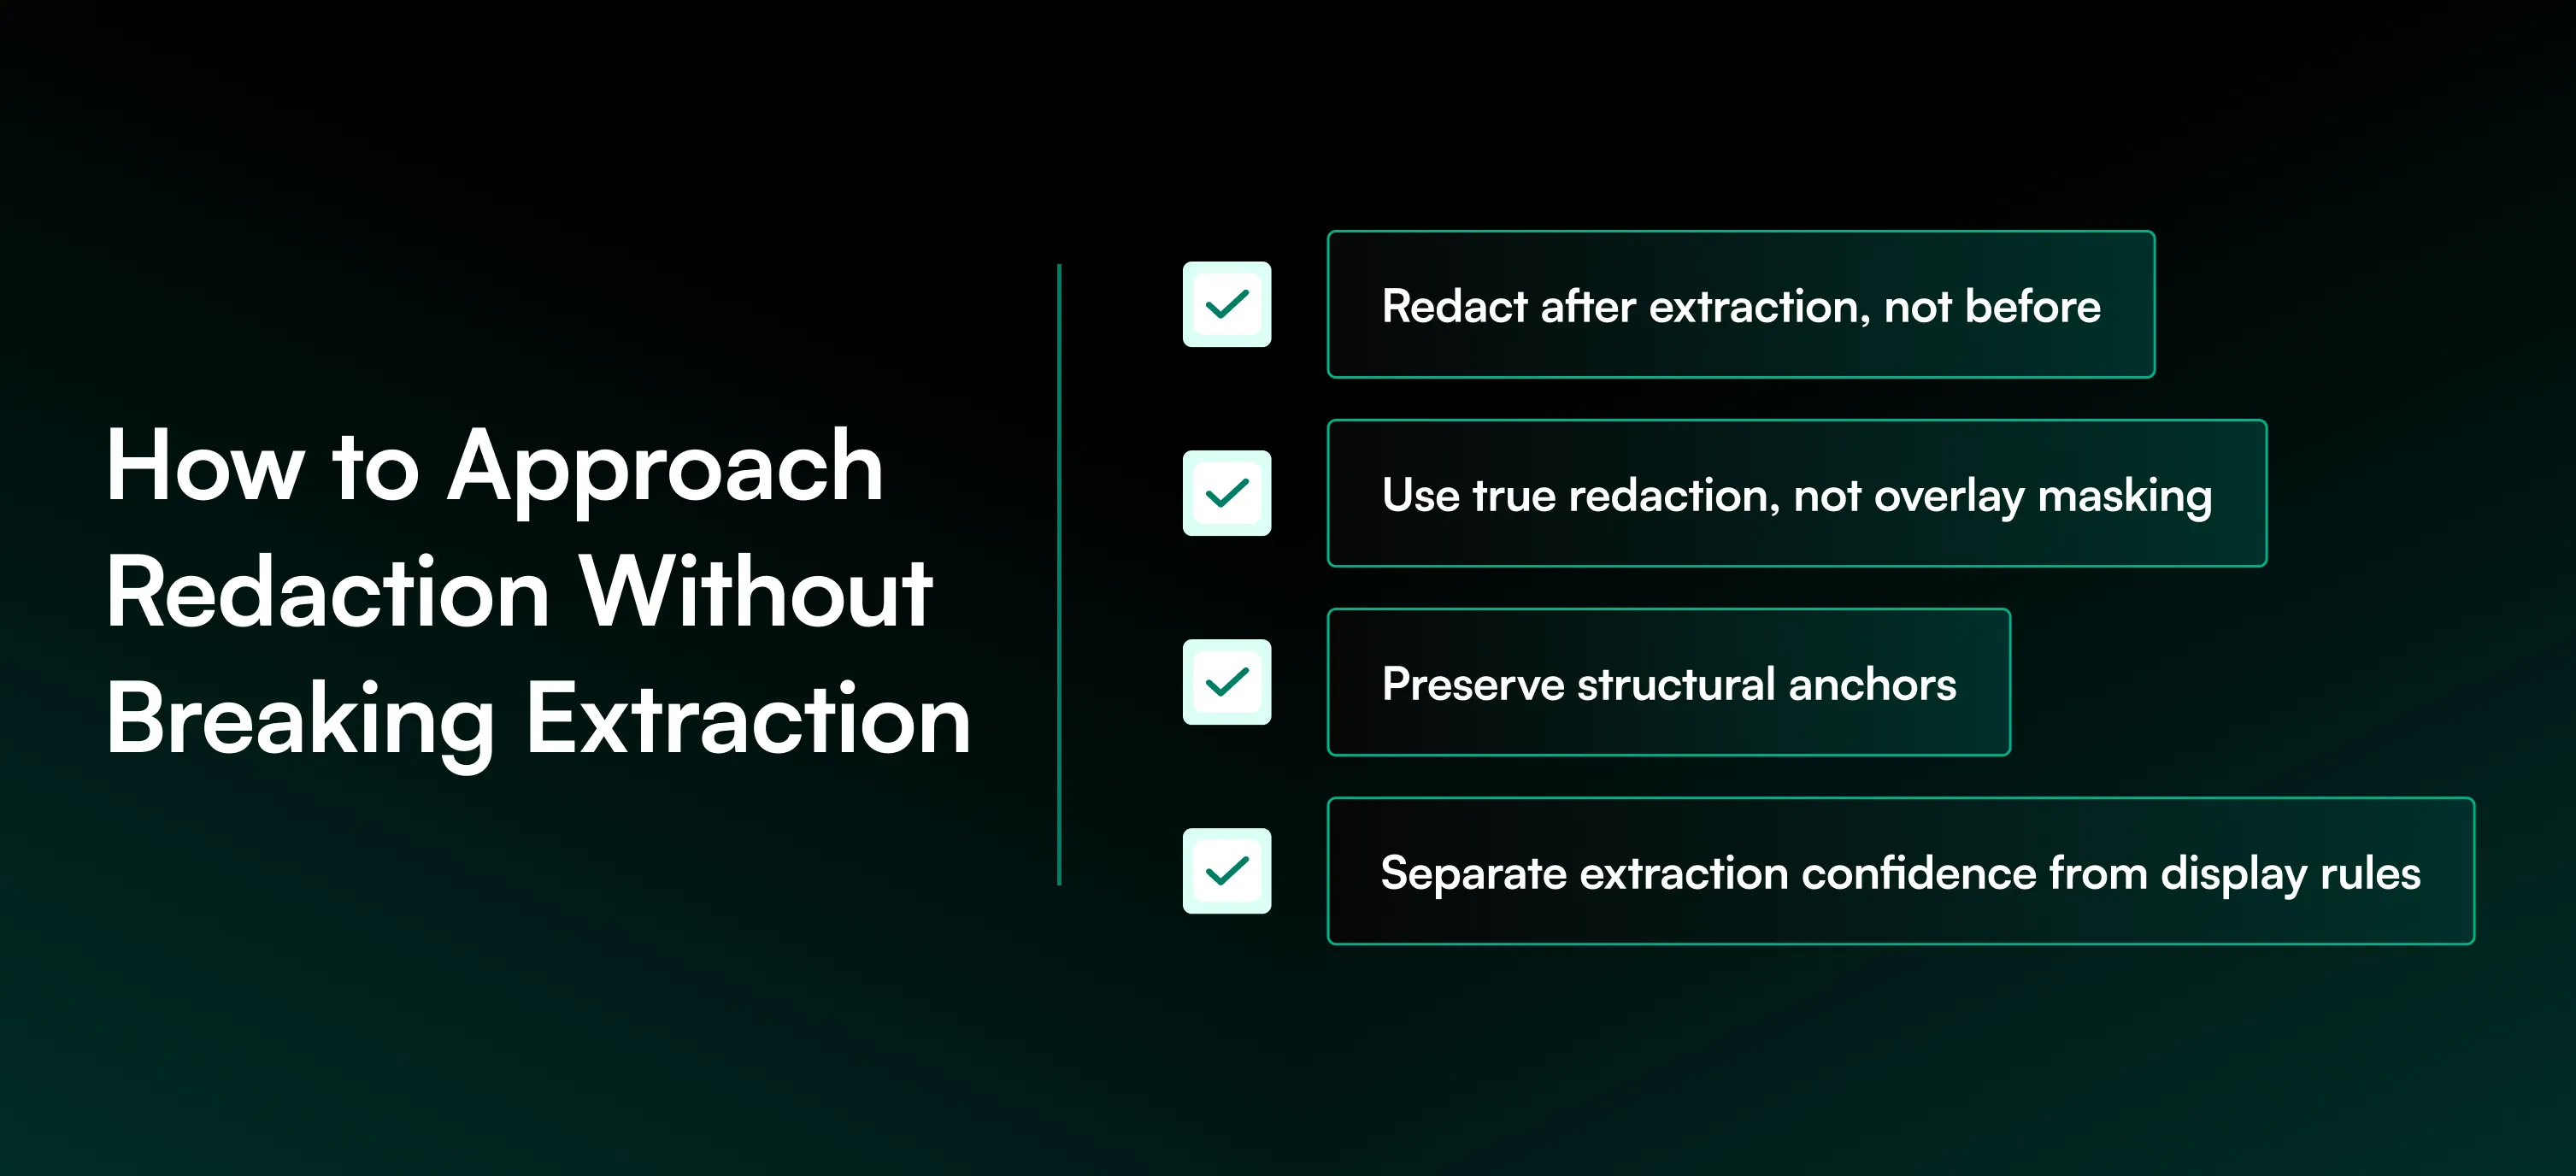
- Redact After Extraction, Not Before: For documents your organization controls, extract required data first, then create the redacted document or display version. This does not apply to source files that arrive already redacted.
- Use True Redaction, Not Overlay Masking: Remove the underlying text or data object instead of placing a visual box over it. The protected value should not remain searchable or extractable.
- Preserve Structural Anchors: Hide sensitive values while retaining useful labels, table boundaries, and surrounding layout where policy permits. This keeps context available for nearby fields.
- Separate Extraction Confidence From Display Rules: Process required data inside controlled systems, then apply role-based redaction to screens, exports, and shared files. Keep extraction logic separate from presentation rules.
How Infrrd Handles Redaction-Aware Extraction
Infrrd supports redaction directly in the document-processing workflow. Teams can configure redaction rules at the document-type level and choose between field-based redaction and keyword-based redaction.
Field-based redaction hides a specific extracted data field, such as a Social Security Number, Account Number, or Total Amount. Once it identifies that field, it can redact its value in the processed document.
Keyword-based redaction hides repeated words or information wherever they appear. This is useful for company names, addresses, confidentiality labels, or other recurring text that needs to be removed across a document.
Configured redactions can be applied automatically during processing. Reviewers can then inspect the result in the correction workflow. If something was missed, they can add a redaction manually. If a box is misplaced or unnecessary, they can adjust or remove it. Redaction actions can also be logged with the document, user, and time without exposing the hidden value in the audit record.
Infrrd can also process documents that arrive already redacted. Because extraction does not depend on fixed templates, the system can work with the remaining text, fields, and structure available in the document.
Example: Processing a Bank Statement
- Configuration: An administrator sets field-based redaction for Account Number and keyword-based redaction for “CONFIDENTIAL.”
- Processing: The document moves through the standard workflow, and configured values and keywords are redacted automatically.
- Review: A reviewer can add, resize, or remove redaction boxes when needed.
- Logging: The system records that redaction actions occurred without storing the protected values in the log.
Redaction can also act as a processing control. Keyword-based redaction can remove repeated company names and addresses from final documents, while field-based redaction can hide an aggregate Total Amount on list bills so the model or HITL reviewer does not mistakenly use it when extracting individual bill amounts.
Summary
Redaction and extraction do not have to work against each other. Problems usually appear when teams treat redaction as a visual editing task instead of a stage in document automation. A secure process removes sensitive data from the version being shared while preserving the structure and context that extraction still needs.
For documents under your control, extraction should usually happen before the redacted output is created. For files that arrive already redacted, the model must work with whatever context remains. Redaction in IDP works best when rules, review, access control, and audit logging are designed together from the start.
FAQs
What's the difference between redaction and data masking?
Redaction permanently removes or sanitizes sensitive information from an output. Masking hides part or all of a value while the original data may remain available.
Can OCR read redacted text?
Yes, if the redaction is only a visual overlay and the underlying text remains. True redaction removes the content so OCR or extraction cannot recover it.
How do you redact a scanned PDF without breaking table extraction?
Extract the required data first where permitted, then apply redaction while preserving table boundaries, labels, and spacing. Avoid deleting structural cues needed for nearby fields.
Is black-box redaction actually secure?
Only if the process removes or sanitizes the underlying data. A black rectangle added as an annotation can leave hidden text searchable, selectable, or extractable.
What documents need redaction in mortgage lending?
Common examples include loan packages shared for investor review, QC, due diligence, legal review, or third-party processing when borrower identifiers are unnecessary for the recipient.
How does redaction affect straight-through processing rates?
Poorly sequenced redaction can remove anchors or identifiers that extraction depends on, which can lower confidence, increase exceptions, and send more documents to human review.
Can IDP systems process documents that are already redacted?
Yes, but extraction quality depends on what remains. If redaction removes labels, identifiers, or layout cues, the system may lose context needed for accurate field matching.
Should sensitive data be redacted before or after extraction?
For documents your organization controls, extraction should generally occur first under proper access controls, followed by redaction of the display, export, or shared document version.